YTL AI Labs and NVIDIA release 1.35 million synthetic Malaysian personas for AI
Malaysian developers get a free dataset for testing whether AI understands the people it serves. The personas are synthetic and built from official statistics, but we could not yet find the public download.
By Utopia Data & AI Team6 min read
In brief
- YTL AI Labs announced Nemotron-Personas-Malaysia on 23 September 2026, an open dataset of 1.35 million synthetic personas developed with NVIDIA.[1]
- YTL says the personas come from 150,000 base records built on official Malaysian statistics, cover 39 fields and contain no personal data.[1]
- YTL says the dataset is on Hugging Face under CC-BY-4.0. On 26 September it was not yet listed in NVIDIA's public Nemotron-Personas collection.[1][3]
What was announced
YTL AI Labs, the AI arm of YTL Power International, announced an open dataset on 23 September 2026 that is meant to help AI systems understand Malaysians. Called Nemotron-Personas-Malaysia, it holds 1.35 million synthetic personas, each a made-up but statistically realistic profile of someone living in the country.[1][4]
The dataset was built with NVIDIA and joins its Nemotron-Personas series. YTL says it is free for commercial use and is the first in the series to lead with Bahasa Melayu.[1]
What is in the dataset
YTL says each persona is generated from probability tables built on published data from the Department of Statistics Malaysia, OpenDOSM, MyCensus, eStatistik and national labour-force publications. It starts with 150,000 base records and expands them into 1.35 million personas, each described across 39 fields.[1]
Those fields cover age, gender, occupation and region, plus personality traits based on the five-factor OCEAN model used in psychology. YTL says no personal data is included and no individual can be identified. The records describe people who could exist, not people who do.[1]
Built to keep Malaysia's diversity intact
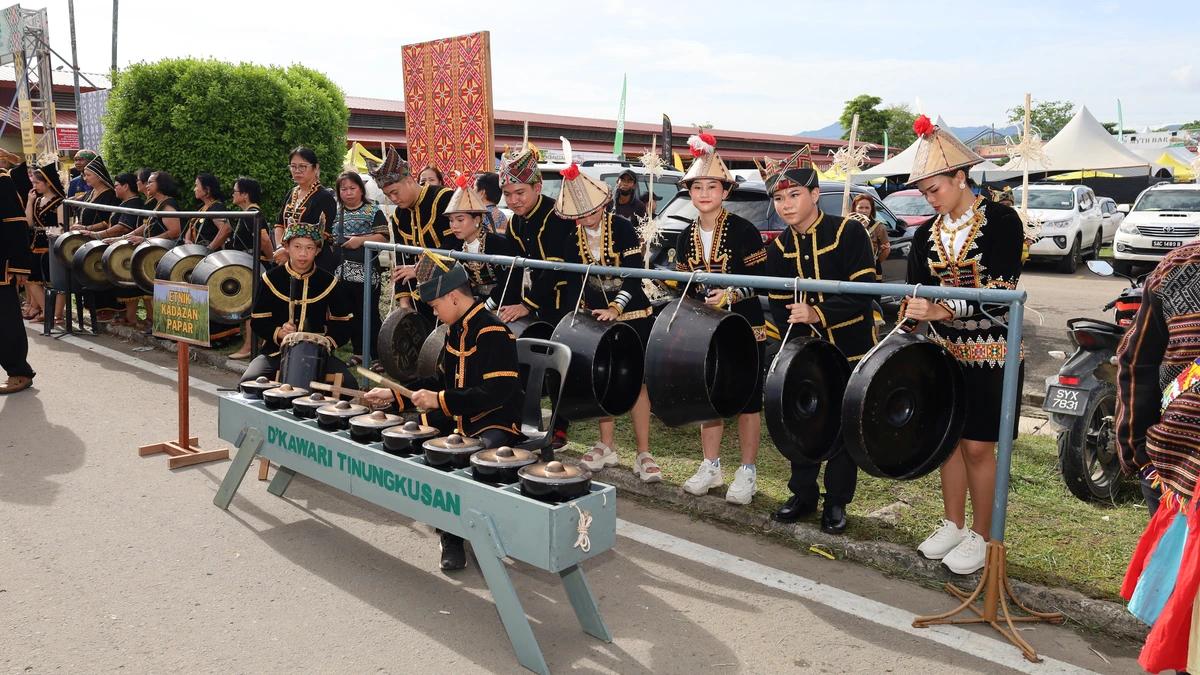
YTL says the method works down to district level. Besides the Malay, Chinese and Indian populations, it keeps the Kadazan-Dusun, Bajau, Murut, Iban, Bidayuh and Melanau communities, with separate Bumiputera categories for Sabah, Sarawak and Peninsular Malaysia rather than one merged group.[1]
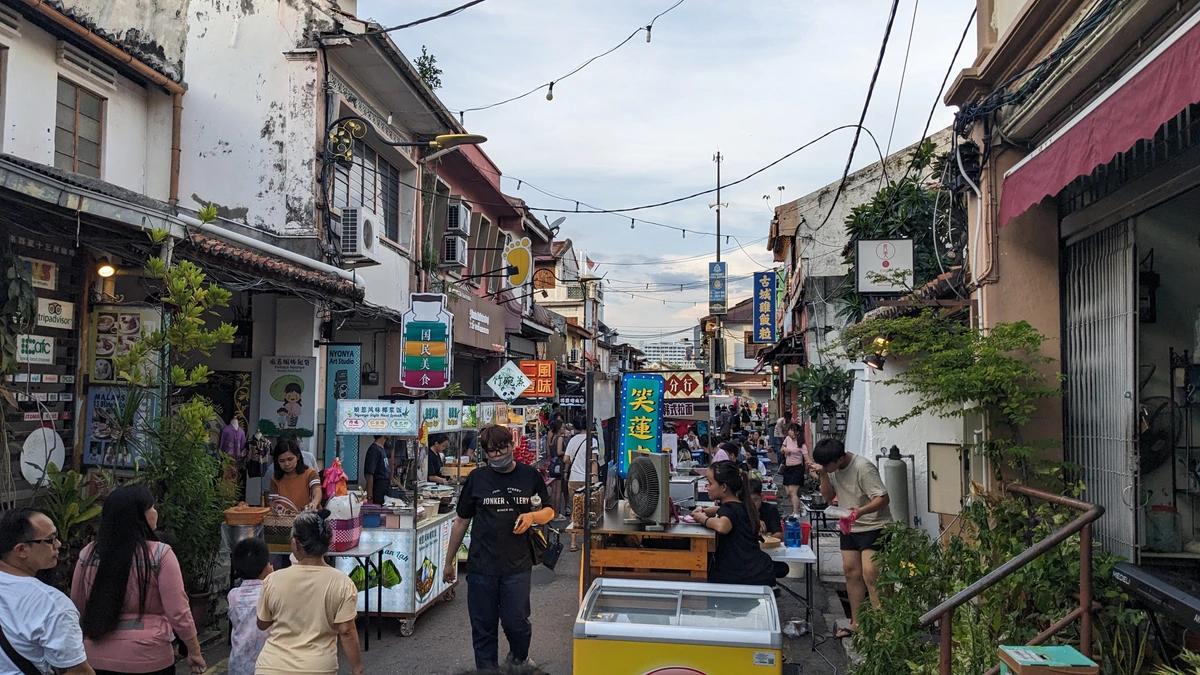
The release illustrates the output with Yunus, a synthetic 39-year-old carpenter in Melaka who earns RM1,873 a month, observes daily prayers and hopes to open a woodcarving workshop. YTL is clear that no real person sits behind him. Every detail comes from published population distributions.[1]
How developers are meant to use it
YTL suggests uses across the development cycle, from generating training data and fine-tuning to alignment, red-teaming and testing. A customer service bot could be tried against synthetic customers of different ages, states and languages. A bank could check whether its AI understands how Malaysians describe financial needs.[1]
Agencies could test whether digital services work equally well across income and demographic groups, and researchers could look for groups a model serves badly. These are the uses the company describes. No Malaysian results from them have been published yet.[1]
Part of a wider NVIDIA push in the region
The dataset uses NVIDIA's NeMo Data Designer library and Nemotron-Personas framework, and follows versions for the United States, Japan, India, Singapore, Brazil, France, Korea, El Salvador, Vietnam and Belgium. On the same day, NVIDIA's AI Day Singapore post said YTL AI Labs is fine-tuning Nemotron models for enterprise and citizen services.[1][2]
For YTL, the personas are one layer of a sovereign AI stack that also includes YTL AI Cloud, its ILMU models and the ILMUchat assistant. Chief executive Foong Chee Mun said the next generation of AI will be defined by "how well intelligence understands the people it serves".[1]
Why Malaysia should care
The dataset is built for Malaysia: it leads with Bahasa Melayu, draws on DOSM statistics and keeps Sabah and Sarawak communities as separate groups. That gives local banks, agencies and SMEs a free way to test AI against the whole country, not a generic user.
Malaysian developers
A free local test set for chatbots and agents.[1]
Practical move: Watch for the official Hugging Face page and read its licence.
Banks and insurers
A way to probe AI for uneven treatment of customer groups.[1]
Practical move: Add persona-based tests before launching customer-facing AI.
Government agencies
Synthetic users to test digital services across groups.[1]
Practical move: Pilot the tests on one service before wider use.
What Malaysians can do now
- Before downloading, confirm the dataset page is published by NVIDIA or YTL AI Labs and note the CC-BY-4.0 attribution terms.
- Pick one live chatbot or form, run it against personas from different states and languages, and record where the answers go wrong.
- Treat synthetic personas as a testing aid, not a substitute for feedback from real Malaysian customers or citizens.
What we still do not know
What we still do not know
- When the public Hugging Face page goes live, and which languages besides Bahasa Melayu it includes.
- How closely the personas match real district statistics, since no independent check has been published.
- Whether any Malaysian bank, agency or company is already using it.
Sources
- YTL AI Labs Launches NVIDIA Nemotron-Personas-Malaysia Dataset with 1.35 Million Synthetic PersonasYTL Community (YTL Corporation), 23 September 2026
- NVIDIA and Partners Showcase AI Advancements Across Southeast AsiaNVIDIA Blog, 23 September 2026
- Nemotron-Personas collectionNVIDIA on Hugging Face
- YTL AI Labs, Nvidia launch open dataset reflecting Malaysia's population diversityThe Star (Bernama), 23 September 2026
- File:Jalan Hang Kasturi during Jonker Street Night Market in Melaka, Malaysia.jpgWikimedia Commons, 3 May 2024
- File:Perarakan etnik Kadazan Papar.jpgWikimedia Commons, 30 May 2024
- File:Market at Jalan Benteng, Kuala Lumpur.jpgWikimedia Commons, 18 July 2025
All three photographs are Creative Commons works from Wikimedia Commons, with licence, author and capture date read live from the Commons API on 26 September 2026. None shows the dataset, YTL or NVIDIA, and none of the people pictured has any known link to them; each caption states what the photograph actually shows. No image was generated, composited or retouched, and framing was the only change made.
Last fact check: 26 September 2026. Factual correction? devteam.utopia@gmail.com.