Cerebras Pairs GPUs With Wafer Chips for AI Inference
Cerebras says it now splits each AI request between GPUs and its own wafer-scale chips, and reports five times more output per megawatt. The figures are the company's, and no price has been announced.
By Utopia Data & AI Team6 min read

In brief
- Cerebras said on 17 November 2026 that disaggregated inference is in production: GPUs process the prompt and Cerebras wafer-scale systems generate the answer, with the company claiming five times more tokens per megawatt at the same speed.[1]
- In Cerebras's own deployment, AMD Instinct GPUs handle the prompt stage and CS-3 systems handle generation. The five-times figure comes from the GPT-OSS-120B shared endpoint, using data from 14 November, and compares against a CS-3-only set-up.[1]
- Amazon Web Services, Fireworks AI, Gimlet Labs and General Compute have early access. Cerebras plans hundreds of megawatts by the end of 2027. The post gives no pricing and carries a note that speed gains may vary.[1]
What Cerebras announced
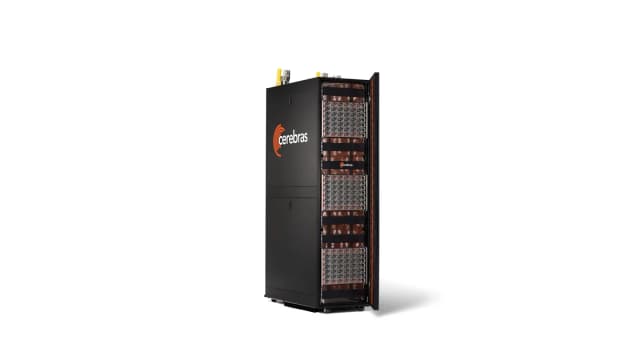
Cerebras has put a split design for AI inference into production. In a blog post dated 17 November 2026, the company said that graphics processors now read the prompt and its own wafer-scale systems write the answer. Cerebras says this gives five times more tokens per megawatt while keeping the same output speed.[1]
In the company's own production deployment on the Cerebras Inference Cloud, AMD Instinct GPUs handle the prompt stage and CS-3 systems handle generation. Cerebras reports the result for the GPT-OSS-120B shared endpoint, using data from 14 November. The post names no customer, price or go-live date for partners.[1]
This story rests on the Cerebras post alone. Every performance figure is Cerebras's own measurement or claim, and the post notes that observed speed gains over GPU-based systems may vary. We did not run any workload on the service.[1]

Why inference is split in two
Cerebras describes inference as two stages. Prefill reads the whole input prompt and produces intermediate model state. Decode then writes output tokens one at a time, and at every step it must read model data from memory again. The post says that repeated reading makes memory bandwidth the main limit on decode speed.[1]
That is where Cerebras argues its chip fits. The post says its wafer-scale processor holds tens of gigabytes of on-chip SRAM and offers tens of petabytes per second of memory bandwidth. It puts that at 350 times the SRAM capacity and 5,400 times the memory bandwidth of a typical GB300 GPU. A diagram in the post, labelled illustrative and not measured, suggests decode runs about ten times faster when weights sit in on-chip SRAM.[1]
What the production result shows
The measured result comes from one deployment. On the Cerebras Inference Cloud, AMD Instinct GPUs run prefill and CS-3 systems run decode. On the GPT-OSS-120B shared endpoint, using data from 14 November, Cerebras says throughput per megawatt was five times that of a configuration using CS-3 systems alone, with no loss in token generation speed.[1]
Two limits apply. The comparison is with Cerebras's own earlier set-up, so it says little about how the new design compares with a GPU-only cluster. It is also one open-weight model on a shared endpoint. The post states no pricing and cites no independent test, so buyers cannot yet turn the five-times figure into a cost per token.[1]

How partners can adopt the design
Cerebras offers two software routes. The end-to-end stack has a framework that routes requests and tracks replica capacity and health, a prefill engine built on open-source engines such as vLLM or SGLang, a Cerebras decode engine, and KV Portal, which moves key-value caches between prefill and decode over RDMA. The post says this route suits partners who want to launch quickly.[1]
The second route is a decode-only SDK for partners who want control. They bring their own prefill engine and framework, and the kit includes a mock decode replica and a reference integration with an open-source framework. Infrastructure partners can also build clusters from a Cerebras reference architecture that places their prefill accelerators beside Cerebras systems on one network.[1]
Rollout and the power argument
Early-access partners are Amazon Web Services, Fireworks AI, Gimlet Labs and General Compute, and Cerebras says it is widening access. It plans to deploy the design across hundreds of megawatts by the end of 2027, in its own Inference Cloud and in partner sites. Interested companies are asked to use a form on the Cerebras website.[1]
The post frames the move as a response to a power squeeze. A chart that cites Goldman Sachs estimates shows AI inference demand growing about 24 times while data centre capacity grows about 2.2 times, with the period running to 2030. Cerebras also points to its recently announced CS-4 system, expanded manufacturing and a planned 700 megawatts of data centre capacity.[1]
Why Malaysia should care
Our analysis: The post names no Malaysian partner, region or price. Malaysian firms are most likely to meet this design indirectly, through a cloud or inference service that adopts it. When you compare providers, ask whether a service runs on split hardware, where it runs and how it is billed.
Malaysian developers and start-ups
A split design could lower the cost of fast model replies if providers pass savings on. No price has been announced and no Malaysian provider is named.[1]
Practical move: Compare reply speed and price across providers on a test workload before you commit.
Data centre and cloud operators
The design pairs GPU prefill with specialised decode hardware and sells output per megawatt, so power use is part of the pitch.[1]
Practical move: Ask hardware suppliers for per-megawatt figures measured on your own models.
IT and procurement leads
The speed claims come from one vendor and one model, and the post says gains may vary.[1]
Practical move: Ask for a trial and measure on your own prompts before you sign.
What Malaysians can do now
- Read the Cerebras post and its footnote on speed claims.
- Ask any inference provider whether it splits prefill and decode across different hardware.
- Test cost and latency on your own prompts instead of relying on a vendor chart.
What we still do not know
What we still do not know
- What the service or partner deployments will cost, and whether customers will see lower prices.
- Which partners will go live first and where their capacity will sit.
- How the design performs against GPU-only clusters in independent tests.
Sources
- Cerebras Launches Disaggregated InferenceCerebras Systems, 17 November 2026
- File:1237 E. Arques Avenue.jpgWikimedia Commons, 7 July 2024
- File:5C2A5953R - 49913961083 – Silicon Wafer 20200519.jpgWikimedia Commons, 19 May 2020
- File:NOIRLab HQ Server Racks (6V6A0402-CC).jpgWikimedia Commons, 5 October 2022
Facts come from Cerebras's blog post of 17 November 2026, read on 19 November. Performance, memory and capacity figures are those the post attributes to Cerebras, and the Goldman Sachs chart is cited by the post, not checked by us. Sections marked as our analysis are Utopia's interpretation. We did not run any workload on the service. The three photographs are licensed contextual images and none shows the hardware in the story. No generated image is used.
Last fact check: 19 November 2026. Factual correction? devteam.utopia@gmail.com.